GPT-6.1 Sol vs Claude Sonnet 5.5: coding workflows and API costs
Compare Sol and Sonnet 5.5 using documented interfaces, cache and long-context prices, task constraints, and reproducible selection criteria—not invented benchmarks.
 Ofox
GPT‑6.1 Sol and Claude Sonnet 5.5 have the same Standard short-context list rates for uncached input and output: $2 and $10 per million tokens. That makes “which model is cheaper?” a workload question. Cache behavior, prompt length, generated tokens, retries, and the cost of adapting your tools can change the answer.
This is a comparison of official specifications, pricing and engineering choices checked on September 30, 2026. It is not a head-to-head coding benchmark. The worked examples deliberately hold token counts constant to isolate price differences; the same source text need not tokenize identically across providers. Neither a vendor benchmark against an older model nor a promotional percentage establishes which of these two models will solve your repository’s tasks better.
What is actually the same—and what is not
| Decision point | GPT‑6.1 Sol | Claude Sonnet 5.5 |
|---|---|---|
| Exact API model | gpt-6.1-sol | claude-sonnet-5-5 |
| Standard short-context uncached input / output, USD per 1M | 2 / 10 | 2 / 10 |
| Cache read, USD per 1M | 0.10 | 0.20 |
| Cache write used in short-TTL example, USD per 1M | 2.50 | 2.50 for 5-minute cache |
| Longer cache option | Current Sol cache documentation uses 30-minute TTL | 1-hour write rate is 4.00 per 1M |
| Long-input pricing | Above 272K input, entire request uses higher rates | Current Anthropic pricing applies standard rates across the supported 1M context for this generation |
| Tool integration discussed here | Responses function calls and call results | Claude-native tool-use and tool-result messages |
| Migration cost | Low if a correct Responses loop already exists | Low if a correct Claude-native loop already exists |
Sources: Sol model details, OpenAI prompt caching, Sonnet 5.5 announcement, and Anthropic pricing. Recheck the exact provider route when using a third-party platform; its price and compatibility are not established by either native API’s documentation.
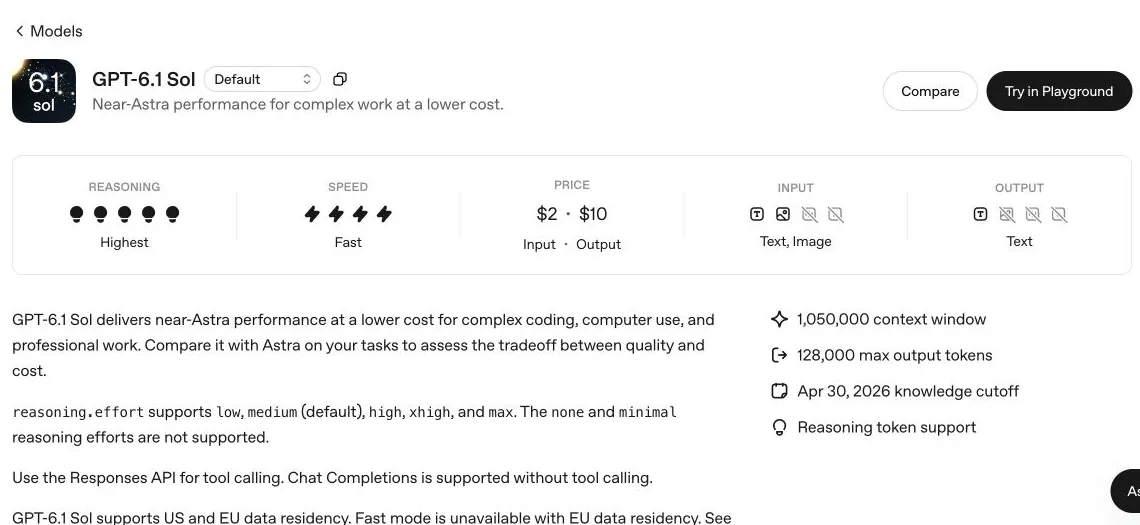
Real English OpenAI documentation screenshot for the Sol side of this comparison. The Sonnet facts are supported by the linked Anthropic text sources; this image is not a comparison run.
Compare three workloads with explicit assumptions
First consider a short, uncached request with 20,000 input and 5,000 output tokens. At Standard rates, both cost $0.04 + $0.05 = $0.09. There is no unit-price winner in that example. If one model needs a second attempt or produces a longer reasoning trace, its actual task cost changes; that requires measured usage, not a conclusion inferred from the shared list price.
Second, consider 10,000 ordinary input tokens, 100,000 cache-read tokens and 5,000 output tokens. Sol costs $0.02 + $0.01 + $0.05 = $0.08; Sonnet costs $0.02 + $0.02 + $0.05 = $0.09. Sol’s cache-read unit rate is half, but the whole request is about 11.1% cheaper under these quantities—not 50% cheaper. This example excludes initial writes and assumes actual hits in each provider’s cache.
For a ten-request sequence, assume a 100K prefix is written once, then read nine times, while each request adds 10K ordinary input and 5K output. Sol’s illustrative total is $1.04. Sonnet’s 5-minute-write illustration is $1.13. That comparison assumes the reads remain eligible under each cache’s own lifetime and matching rules. It is not a claim that a Sonnet cache survives an arbitrarily spaced session. A 1-hour write changes the Sonnet total, while missed reads change both totals.
Third, take a 300,000-token uncached input and 10,000-token output. Sol crosses its threshold and costs $1.20 + $0.15 = $1.35. At Sonnet’s documented standard rates for its supported context, the corresponding arithmetic is $0.60 + $0.10 = $0.70. This is a useful cost signal for long-document workloads, but it does not establish equivalent extraction accuracy or even that every real request fits the provider’s limits once tool definitions and output reserve are included.
Keep these cases separate. A short coding diff, a cache-heavy agent session, and a long repository dump are different workloads. Quoting one percentage for all three hides the condition that produced it.
Your tool stack can decide the first candidate
If your application already uses OpenAI Responses with a verified multi-turn tool loop, Sol is a natural first candidate because the integration is closer. Check the restrictions nonetheless: Sol tool calling requires Responses, and a Chat Completions wrapper that formerly worked with another model can fail. Our complete migration example shows the returned items, call IDs and bounded dispatcher.
If your production agent already uses Claude-native tools, retaining Sonnet as the first candidate can reduce protocol work. Tool schemas, response events, state handling and cache controls must be checked when changing providers. An OpenAI-compatible gateway may translate some of these details, but the translation itself becomes part of the system under test. A successful plain-text request does not prove tool compatibility.
Estimate engineering effort separately from inference. For example, a small team making a low volume of calls may spend more validating a new tool protocol than it saves on a modest cache-read difference. A high-volume service can reach the opposite conclusion. Use your own traffic and engineering estimates; this article does not assign an invented hourly cost or migration duration to your team.
Choose by task and available validation
| Task situation | Reasonable first experiment | Evidence required before adopting |
|---|---|---|
| Existing Responses agent with narrow bug fixes | Sol using the current tool harness | Passing regression tests, correct tool results, acceptable review effort |
| Existing Claude workflow for routine coding and document work | Sonnet in that same workflow | Acceptance of actual code or exported files, no missing requirements |
| Large uncached document or repository input | Compare both, with long-context pricing enabled | Source-grounded answers, missed-fact count, full usage ledger |
| Cache-heavy repeated work | Compare achieved hit rates and end-to-end task cost | Writes, reads, misses, output and retries—not cache price alone |
| Irreversible or high-impact operation | Start with a read-only proposal and verification gate | Authorization and action correctness, independent of model brand |
These are experimental starting points derived from integration and pricing conditions, not measured superiority claims. Anthropic positions Sonnet 5.5 for well-scoped everyday tasks, bug fixes and polished documents; OpenAI positions Sol for complex work at lower cost than Astra. Those vendor descriptions help choose tests, but they do not replace the tests.
The Sonnet launch announcement’s speed and task-cost improvements compare Sonnet 5.5 with Sonnet 5. They cannot be relabeled as improvements over GPT‑6.1 Sol. Likewise, “near-Astra” does not establish a Sonnet-versus-Sol result. We omit a leaderboard table because results from different harnesses, tools and reasoning budgets would look more comparable than they are.
A comparison protocol you can reproduce
Start with a fixed set of representative tasks drawn from work you actually accept: a failing test with a defined expected behavior, a small feature with constraints, a refactor with regression tests, and a source-grounded document task. Use a disposable branch or synthetic repository. Remove credentials and private customer data before using any external service.
For every task, give both systems the same allowed files, tool permissions, acceptance criteria and stopping condition. Record the model ID, client/provider, date, reasoning settings, instructions and environment. Reasoning-level names across providers are not calibrated units of effort, so report the settings explicitly rather than claiming that matching names make the compute identical.
Measure accepted outcomes first. For code, run the relevant tests and inspect the diff for unrelated changes, missing error handling and security-sensitive behavior. For documents, check required sections, cited evidence and the actual output file. Then record token cost, tool charges, elapsed time, retries and human correction time. Do not count an enthusiastic final message as a completed task.
Repeat enough tasks to expose variation and report the sample size, including failures. A small pilot can justify a local deployment decision but not a universal “best coding model” headline. Keep a rollback path and rerun the evaluation after changing the harness or model version. Otherwise, improvements caused by a tool update may be incorrectly credited to a model.
When to choose one, both, or neither yet
Start with the model that fits your validated tool stack when short-request pricing is equal and switching has no demonstrated benefit. Test Sonnet carefully for large uncached inputs where its documented pricing has an advantage. Test Sol for cache-heavy Responses workflows, while including cache writes and misses. Consider routing only when you can reliably identify failures and the extra operational complexity has a measured payoff.
If you lack an acceptance test, adding a second model does not solve the evaluation problem. Build a checkable task first. For harder work inside the OpenAI family, the Sol-versus-Astra decision guide explains escalation arithmetic. For detailed billing conditions, use the Sol pricing guide. Current Ofox availability and pricing must be checked separately; no Ofox discount or compatibility claim is implied here.