MiniMax M3 vs GPT-5.5: SWE-Bench Pro, 8× Price Gap, A/B Both via ofox (2026)
MiniMax M3 (SWE-Bench Pro 59.0%) vs GPT-5.5 (58.6%): same 1M context, $0.60 vs $5 input, $2.40 vs $30 output.
MiniMax M3 vs Claude Opus 4.8: 59% vs 69% SWE-Bench, 10× Pricing, Pick (2026)
MiniMax M3 hits 59% on SWE-Bench Pro vs Claude Opus 4.8 69.2%. M3 input $0.6/M vs Opus $5/M, output $2.4/M vs $25/M, both 1M context.
DeepSeek V4 Pro Real Cost: 120x Cache Gap Behind Sticker
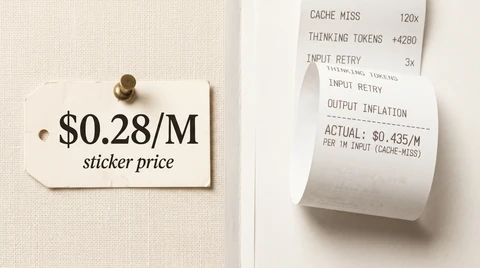
V4 Pro lists at $0.435/M input — cache misses cost 120x more than hits, and thinking inflates output. Benchmarked vs GPT-5.5 and Sonnet 4.6 with raw data.
Claude Code /cd: Switch Directories, Preserve Prompt Cache, 3 Edge Cases (2026)
Claude Code /cd switches directories mid-session and keeps the prompt cache hot. Three edge cases break it: CLAUDE.md drift, MCP drift, /add-dir conflicts.
Claude Code Nested Sub-Agents: 5 Levels Deep, Token Math, 3 Pitfalls (2026)
Claude Code v2.1.172 lets sub-agents spawn sub-agents five levels deep. Token costs compound per branch, and three anti-patterns make the bill run away.
Claude Code Safe Mode: 5 Things Disabled + When to Use Over /clear (2026)
Claude Code v2.1.169 --safe-mode: 1 flag disables 5 layers (CLAUDE.md, plugins, skills, hooks, MCP). Differs from /clear (1-turn wipe).
Claude Fable 5 vs Opus 4.8 vs GPT-5.5: SWE-Bench, Pricing, When to Switch
Fable 5 hits 95.0% SWE-bench Verified and 80.3% SWE-bench Pro — 11 points over Opus 4.8, 21.7 over GPT-5.5. At $10/$50 it costs 2x Opus.
Codex AGENTS.md Not Loading in Symlinked Workspaces: v0.138 Fix (2026)
Codex CLI v0.138 finally loads AGENTS.md in symlinked and remote workspaces. Three verification steps, seven error patterns, and the monorepo fix.
Anthropic vs OpenAI Prompt Caching 2026: Cost Math + 3 Cache-Miss Fixes
Anthropic and OpenAI both price cache reads at 0.1x input, but writes and TTLs differ. Three cache-miss patterns and the cost math on 10M tokens a day.
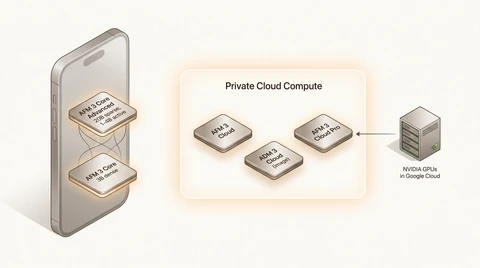
Apple's Third-Generation Foundation Models: A Developer's Read on WWDC 2026
Apple's AFM 3 at WWDC 2026: five models, a 20B sparse on-device LLM, and Private Cloud Compute on NVIDIA GPUs. What is verified, what is spin.